Don't let a traffic spike turn into a site crash. Learn how ecommerce infrastructure scalability and rigorous holiday web traffic testing protect your revenue during the busiest shopping days of the year.


The annual surge of online shoppers is no longer just a busy weekend. It is a full-scale stress test for your digital foundations. By the end of 2026, global retail eCommerce sales are projected to exceed 7 trillion dollars, with peak holiday windows accounting for a massive portion of that volume. If your systems are not optimized, that growth represents a risk rather than an opportunity. A single minute of downtime during a flash sale can cost more than your entire annual IT budget. This makes ecommerce infrastructure scalability the most critical metric for your technical team this season. To survive the rush, you need to move past hoping for the best. You need a rigorous and data-driven approach to ensure your tech stack can handle the load without breaking. This checklist breaks down the essential technical pillars of holiday readiness, from the database to the edge.
Validating Performance and Capacity
You cannot fix what you have not broken in a controlled environment. Many teams make the mistake of testing for average high traffic, but holiday spikes are rarely average. They are unpredictable, sudden, and often sustained for hours. Effective holiday web traffic testing involves simulating various scenarios. Start with a baseline stress test to find your absolute breaking point. Once you know where the system fails, whether it is the database connections or the API gateway, you can begin building in redundancies. You should also run soak tests. These tests maintain a high load over a long period to check for memory leaks or gradual performance degradation.
The goal of holiday web traffic testing is to understand the ceiling of your current architecture. If you find that your checkout service starts to lag when you hit ten thousand concurrent users, you have a clear target for optimization. Do not wait until Black Friday to discover these limitations. Testing early gives your developers enough time to refactor inefficient code or adjust your load balancing rules.
Scaling is not just about adding more servers. It is about adding the right resources in the right places. Server capacity planning requires a deep dive into your historical data from previous years, adjusted for your projected growth.
Analyze your CPU utilization, memory consumption, and disk I/O from last year’s peak. If you are running on a microservices architecture, identify which specific services are the hungriest. Often, a single bottleneck in a checkout service or a search index can bring down the entire frontend, regardless of how many web servers you have active. Ensure your auto-scaling groups are configured with aggressive triggers so they spin up new instances before the latency starts to impact the user experience. Good server capacity planning also involves looking at your third-party integrations. Your internal systems might be ready to scale, but can your payment processor or your shipping API handle the same volume? Part of your plan should involve communicating your expected traffic numbers to your partners to ensure there are no weak links in the chain.
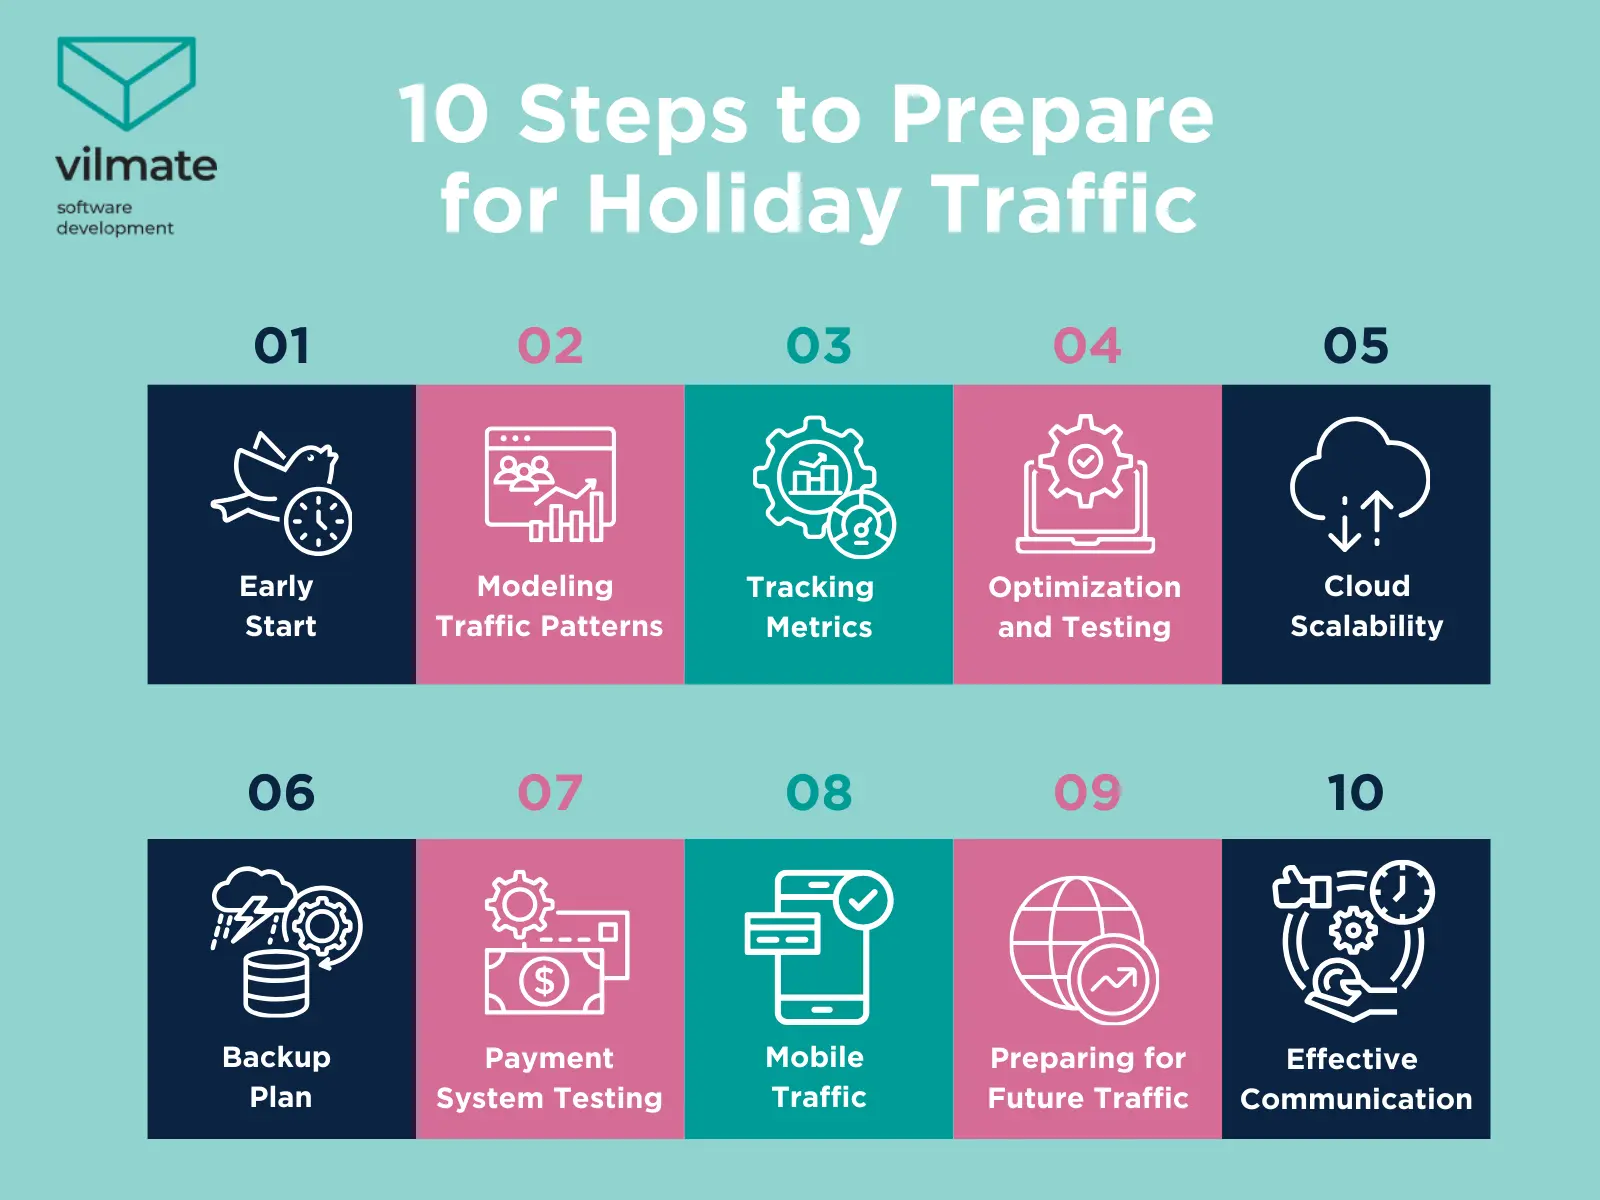
In a high-traffic environment, if something goes wrong is the wrong question. The right question is when. Cloud native disaster recovery is your insurance policy against the worst-case scenario. This goes beyond simple backups. It means having a fully automated failover process.
Relying on manual intervention during an outage is a recipe for disaster. Your recovery strategy should include multi-region deployments. If a primary data center faces an outage, your traffic should automatically reroute to a secondary region with minimal data loss. Test these failovers now. A recovery plan that has not been tested under simulated pressure is just a document, not a solution.
True cloud native disaster recovery also includes the ability to roll back deployments instantly. If a last-minute code change causes a memory leak during a peak shopping hour, your CI/CD pipeline must allow for a one-click reversal. Maintaining high availability is about speed of recovery just as much as it is about preventing failure.
The database is frequently the first thing to fail during a traffic spike. While you can scale web servers horizontally with ease, scaling a relational database is much more complex. Look at your most expensive queries. During the holidays, your product catalog and inventory systems will be hammered. Implement aggressive caching strategies using tools like Redis or Memcached to take the load off your primary database. If you have not already, consider read-replicas for your product pages so that the main write-database is reserved strictly for transactions and checkouts. Reducing the number of direct database hits is the most effective way to ensure ecommerce infrastructure scalability when thousands of users are hitting the add to cart button simultaneously.
Another aspect of database health is connection pooling. During a spike, your application may try to open more connections than the database can handle, leading to a total lockout. Properly configuring your connection pools and setting realistic timeouts will prevent the database from becoming a black hole for incoming requests.
Your origin server should do as little work as possible. Use a Content Delivery Network or CDN to serve all static assets including images, CSS, and JavaScript from locations physically closer to your users. Modern CDNs can even handle basic logic at the edge, such as image optimization or A/B testing. This significantly reduces the latency for the end user and saves your server resources for dynamic tasks like processing payments. Double-check your Cache-Control headers to ensure that everything that can be cached is being stored at the edge for as long as possible.
When you offload the majority of your requests to the edge, you gain significant ecommerce infrastructure scalability. It allows your core servers to focus entirely on the checkout logic and personalized user data, which are the parts of the journey that actually generate revenue.
Even the best holiday web traffic testing cannot account for every variable. When an anomaly occurs, your team needs a clear war room protocol. Establish an on-call rotation that covers 24/7 during your peak days. Every engineer should know exactly who to contact for specific issues, whether it is a third-party payment gateway failure or a localized DNS issue. Clear communication channels, like a dedicated chat room or a real-time dashboard, prevent the chaos that usually follows a technical hiccup. Your incident response should also include pre-written communication templates for your customers. If the site does go down, being able to post an update immediately helps maintain trust. Technical readiness is as much about people and processes as it is about servers and code.
Long-term success depends on how well you learn from each peak. As soon as the holiday rush ends, your team should conduct a thorough post-mortem. Collect all the data regarding latency, error rates, and server costs. Use these insights to refine your server capacity planning for the following year. By treating infrastructure as an evolving asset rather than a set-it-and-forget-it system, you create a resilient environment that can handle any growth the market throws at you. In a world where digital performance is synonymous with brand reputation, your infrastructure is your most valuable competitive advantage.
While much of this checklist focuses on the backend, the frontend plays a massive role in perceived performance. During high traffic periods, users are often on mobile devices or slower networks. If your site takes too long to become interactive, they will leave.
Optimize your JavaScript bundles and ensure you are using modern image formats like WebP. Lazy loading should be implemented for all below-the-fold content. When the frontend is lightweight, it places less stress on the backend APIs because users are not constantly refreshing pages in frustration. This synergy between frontend efficiency and backend server capacity planning is what creates a truly seamless shopping experience.
Finally, ensure your security protocols are up to date. High-traffic periods are a favorite time for DDoS attacks because attackers know your systems are already under pressure. Ensure your cloud native disaster recovery and security layers include automated DDoS mitigation. By protecting your availability, you protect your revenue. Achieving true ecommerce infrastructure scalability is a continuous journey. It requires a culture of testing, a commitment to modern cloud practices, and a deep understanding of your specific traffic patterns. By following this checklist, you are not just preparing for a busy season. You are building a foundation for sustainable growth and a better experience for every customer who visits your site.
Blue Coding is a specialized software development firm focused on helping companies scale their technical teams and infrastructure with ease. Whether you need a dedicated pod of engineers to overhaul your backend or specialized DevOps experts to manage your cloud migration, we provide the high-level talent required to solve complex problems. We understand the unique challenges of building for high-growth environments and offer a seamless way to augment your existing team with top-tier developers from Latin America. If you are concerned about your current system's ability to handle the next big traffic spike, we are here to help. We offer a first free call for queries to discuss your technical bottlenecks and provide a roadmap for your next phase of growth. Contact us today to book your call!


Subscribe to our blog and get the latest articles, insights, and industry updates delivered straight to your inbox